When to adapt a model
Fine-tuning continues training on selected data to improve behavior or domain performance. Prompting or RAG may be enough for some tasks. Fine-tuning is not a dependable substitute for retrieving current facts or enforcing access control.
Full tuning and PEFT
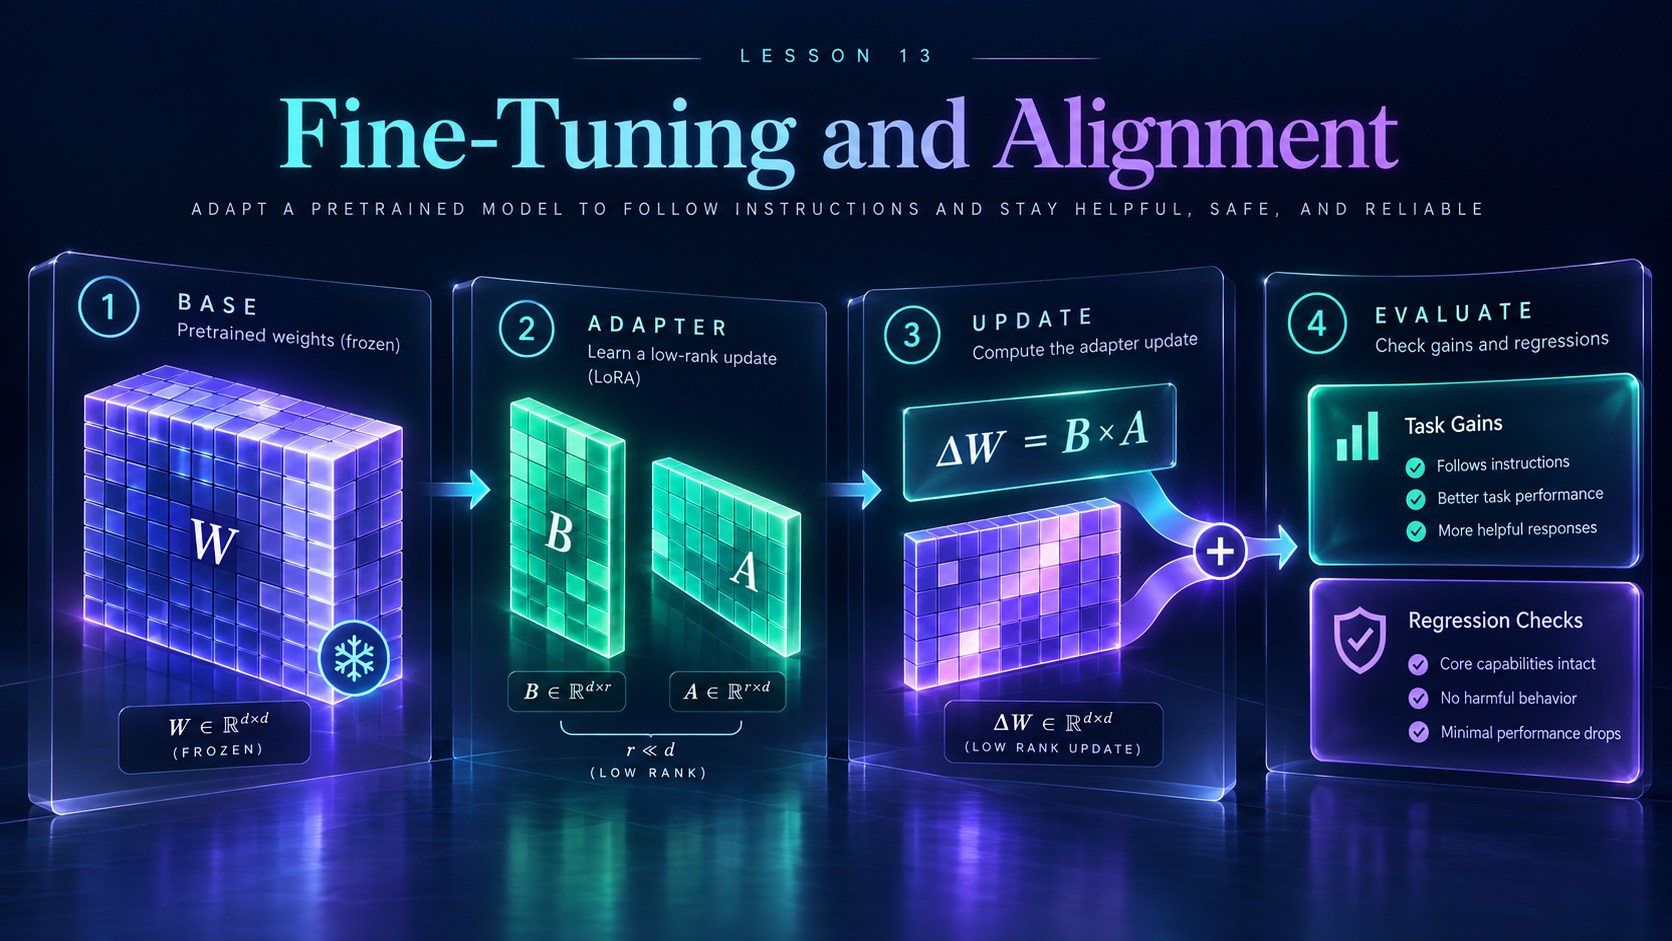
Full fine-tuning updates all selected model weights. Parameter-efficient fine-tuning updates a smaller parameter set. LoRA learns low-rank updates to selected matrices; adapters insert trainable modules. Soft prompt and prefix tuning optimize trainable representations, not ordinary typed prompts.
Instruction and preference training
Supervised instruction tuning learns from input/target pairs. RLHF uses human preference information in a reinforcement-learning pipeline. DPO uses preference pairs with a different optimization objective.
Constitutional approaches use explicit principles in feedback or training. None guarantees that every output is safe or correct.
QLoRA and evaluation
QLoRA combines a frozen quantized base with trainable low-rank adapters and supporting memory-saving techniques. Validate task gains, general capability retention, robustness, and evidence fidelity on held-out examples; monitor overfitting and regression.
Worked example
For a two-by-two base matrix, a rank-one update is the outer product of B and A. Real LoRA also uses a scaling factor and targets selected model layers.
Download lesson 13 Python example
W = [[1, 0], [0, 1]]
B = [[1], [2]]
A = [[0.1, 0.2]]
delta = [[B[i][0]*A[0][j] for j in range(2)] for i in range(2)]
adapted = [[round(W[i][j]+delta[i][j], 2) for j in range(2)] for i in range(2)]
print("Adapted:", adapted)
d_in, d_out, rank = 1000, 1000, 8
print("Full parameters:", d_in*d_out)
print("Adapter parameters:", rank*(d_in+d_out))
Expected output
Adapted: [[1.1, 0.2], [0.2, 1.4]]
Full parameters: 1000000
Adapter parameters: 16000
The adapted matrix is [[1.1,0.2],[0.2,1.4]]. A 1,000-by-1,000 matrix has one million parameters; rank-eight A and B together have 16,000. This counts trainable adapter parameters, not total model memory.
Practice and self-check
Common mistake
A small training set of preferred answers can cause memorization or regressions. Keep validation/test cases separate and compare with the original model.
Student tasks
- Change the adapter rank in the parameter-count calculation to 16.
- Decide whether a frequently changing price list is better handled through retrieval or weight updates, and explain.
- Specify three held-out tests for an instruction-tuned support assistant.
Checkpoint — open after attempting the tasks
Rank 16 uses 32,000 adapter parameters. A changing price list is generally better read from an authoritative current data source.