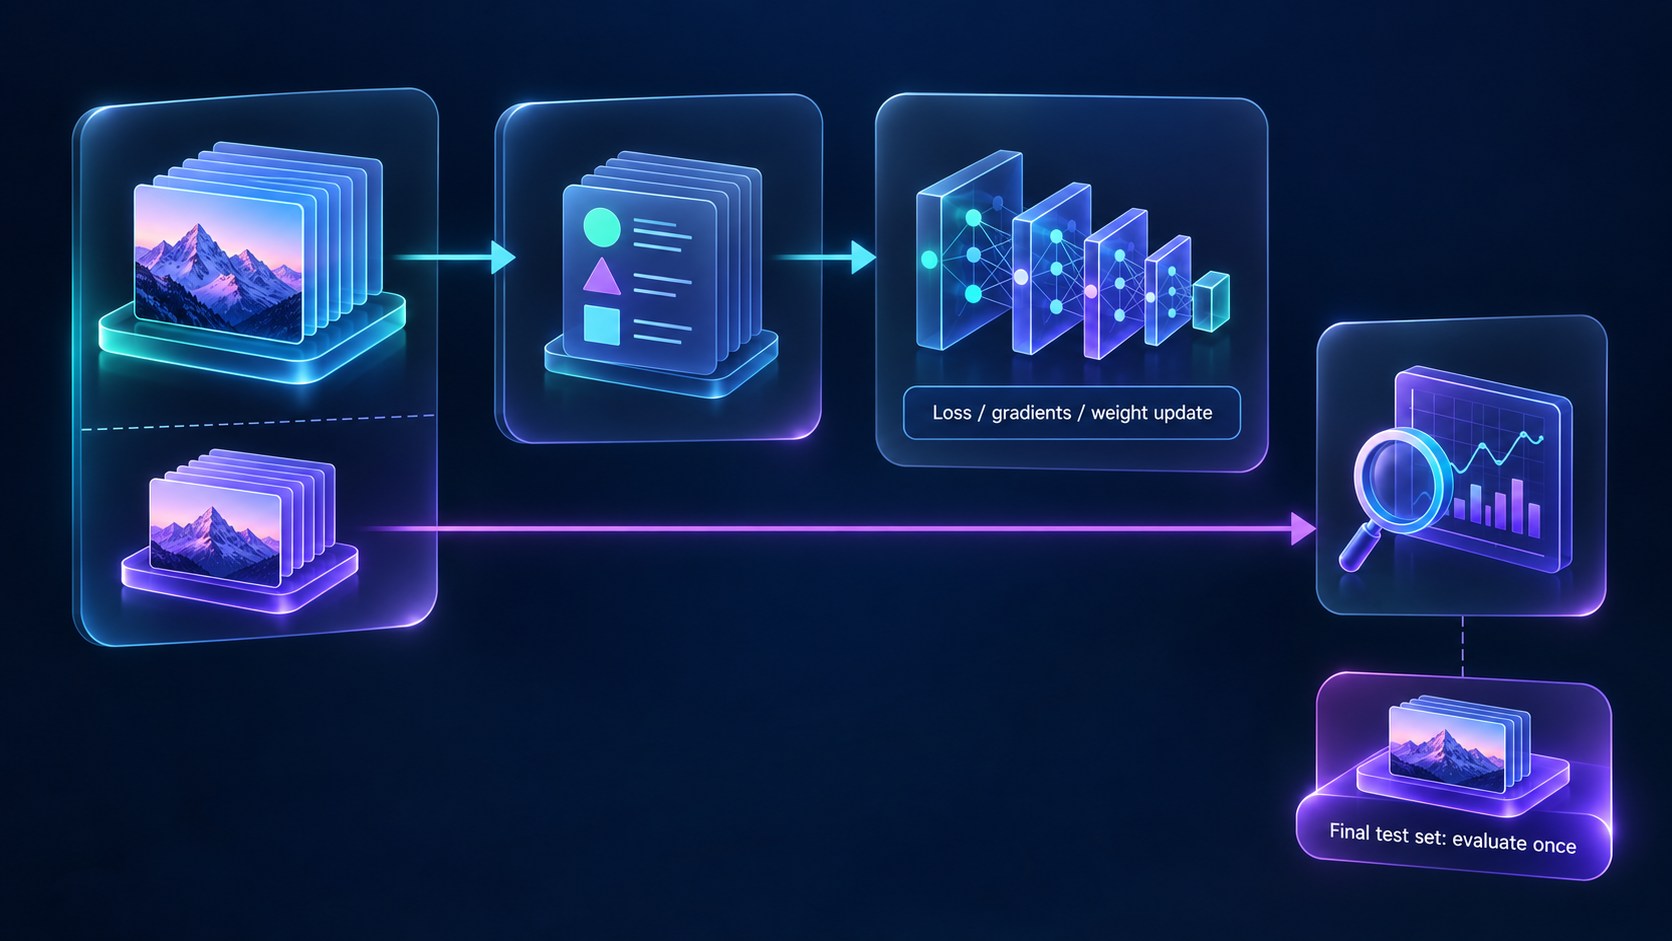
Prepare trustworthy data
Collect suitable data, deduplicate it, filter undesirable material, and respect applicable data rights and privacy requirements. Separate training, validation, and test data before evaluations can leak into training.
Tokenization makes text consumable by the model.
Create prediction targets
For tokens [The, cat, sat, EOS], a causal training sequence uses [The, cat, sat] as inputs and [cat, sat, EOS] as shifted targets. The text supplies its own labels, making this self-supervised learning.
Optimize the loss
Cross-entropy for a correct next token is -log(p_correct). Average over eligible positions. Backpropagation computes gradients; an optimizer updates weights. Validation checks progress without using those examples for gradient updates.
From base model to deployment
After pretraining, instruction tuning and preference optimization may adapt behavior. Evaluate before release and monitor afterwards. Large training runs can use data, tensor, or pipeline parallelism; the right design depends on the workload.
Worked example
The probabilities of three correct target tokens are 0.8, 0.5, and 0.25. We compute their average negative log probability and the corresponding perplexity.
Download lesson 08 Python example
from math import log, exp

sequence = ["The", "cat", "sat", "<EOS>"]
print("Inputs:", sequence[:-1])
print("Targets:", sequence[1:])
p_correct = [0.8, 0.5, 0.25]
loss = -sum(log(p) for p in p_correct)/len(p_correct)
print("Loss:", round(loss, 3))
print("Perplexity:", round(exp(loss), 3))
Expected output
Inputs: ['The', 'cat', 'sat']
Targets: ['cat', 'sat', '<EOS>']
Loss: 0.768
Perplexity: 2.154
The loss is about 0.768 and perplexity about 2.154. Higher probability on the correct tokens lowers loss.
This calculation demonstrates the objective; it does not train a neural network.
Practice and self-check
Common mistake
A low training loss can coexist with overfitting. Evaluate on held-out data, and do not compare perplexity across incompatible tokenizations as if it were the same measurement.
Student tasks
- Recalculate using probabilities [0.9,0.9,0.9].
- Create shifted inputs and targets for a different four-token sentence.
- Explain why exact duplicates across training and test sets can inflate results.
Checkpoint — open after attempting the tasks
With all correct-token probabilities 0.9, loss is about 0.105 and perplexity is about 1.111.