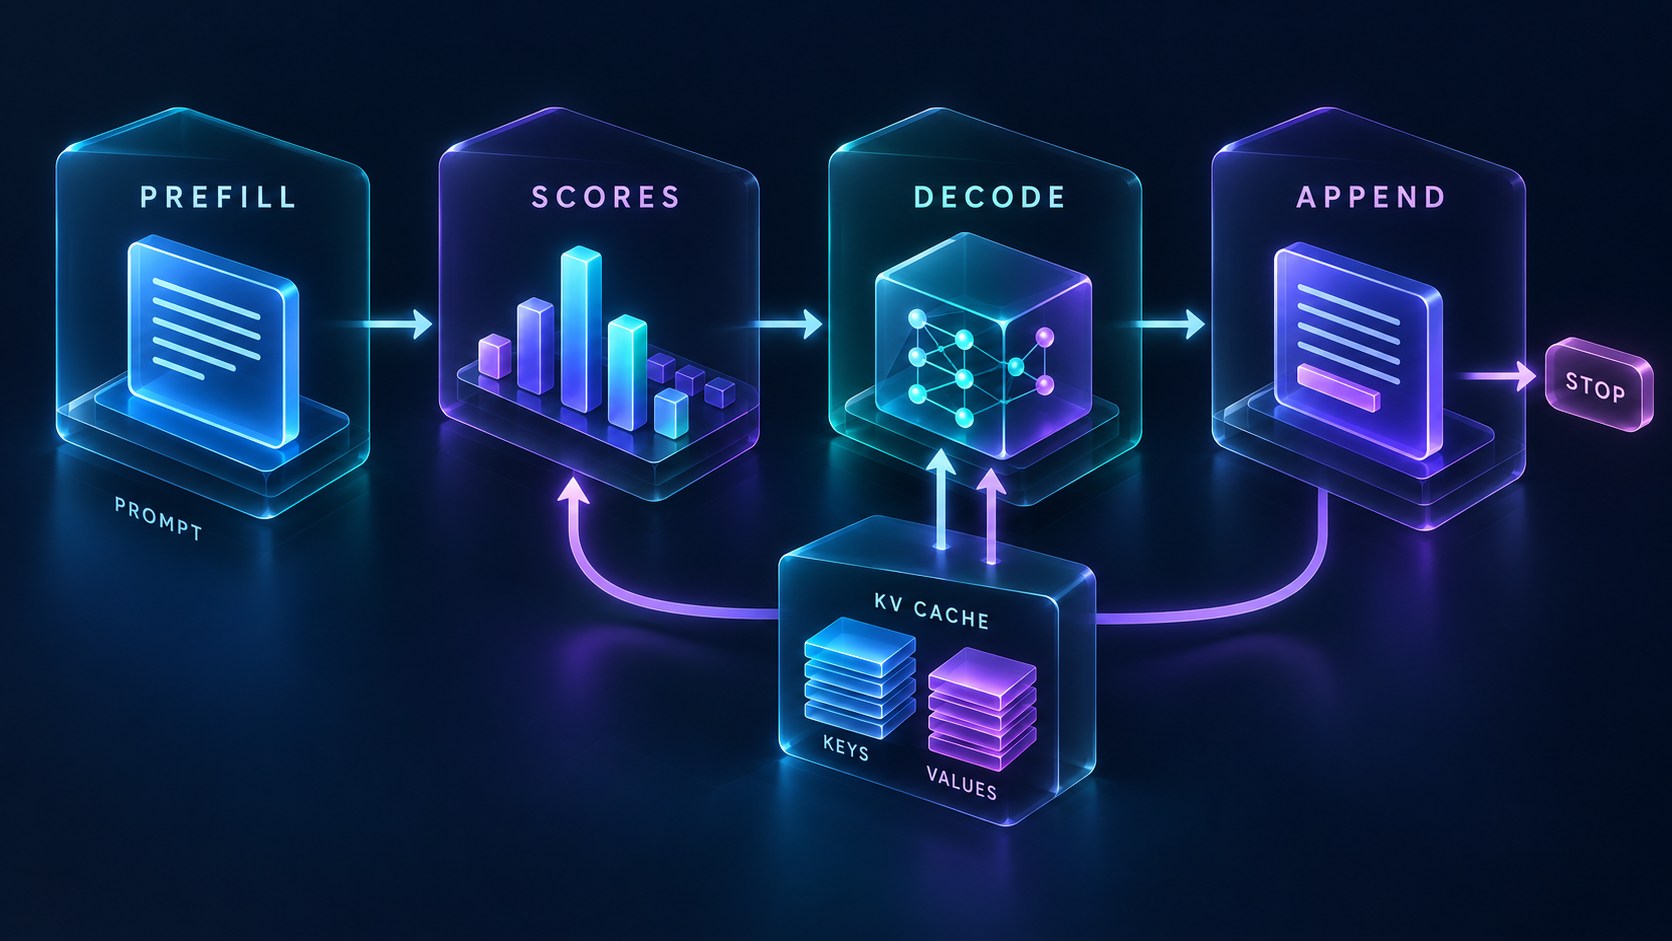
Prefill and decoding
Prefill processes the prompt. Decoding extends the answer token by token. A key/value cache stores earlier attention keys and values so they need not be recomputed in full for every step; it still consumes memory.
Choosing the next token
Greedy decoding selects the largest score. Sampling draws from a probability distribution. Top-k keeps a fixed number of candidates. Top-p keeps the smallest high-probability set whose cumulative mass meets the threshold, then renormalizes for sampling.
Temperature and stopping
Temperature rescales logits before softmax: lower positive values sharpen the distribution. It does not guarantee correctness or full reproducibility. Stop at EOS, a supported stop sequence, or a configured generation limit.
Efficiency trade-offs
Batching, efficient kernels, quantization, and speculative decoding can improve serving performance. Benefits depend on hardware, workload, and implementation. Quantization can change quality. Beam search retains multiple candidate sequences but is not universally best for chat.
Worked example
Given a next-token distribution, we build a top-p candidate set at 0.7. The first two candidates total 0.75, so both are retained.
Download lesson 09 Python example
probabilities = {"blue": 0.50, "gray": 0.25, "clear": 0.15, "dark": 0.10}
p = 0.70
kept, mass = [], 0.0
for token, probability in sorted(probabilities.items(), key=lambda x: -x[1]):
    kept.append((token, probability))
    mass += probability
    if mass >= p:
        break
print("Greedy:", max(probabilities, key=probabilities.get))
print("Top-p:", [(t, round(v/mass, 3)) for t, v in kept])
Expected output
Greedy: blue
Top-p: [('blue', 0.667), ('gray', 0.333)]
The retained probabilities become about 0.667 and 0.333 after renormalization. A subsequent sampling step would choose between them; the code only constructs the distribution.
Practice and self-check
Common mistake
Do not confuse maximum output tokens with total context capacity. A larger output allowance can raise latency without fixing a poor prompt.
Student tasks
- Run with top-p=0.9 and identify the retained tokens.
- Explain how top-k=2 differs from top-p=0.7 when the distribution changes.
- Name two useful latency measurements for a chat application.
Checkpoint — open after attempting the tasks
At 0.9 the first three tokens are retained. Useful measurements include time to first token, generation tokens per second, and total response time.