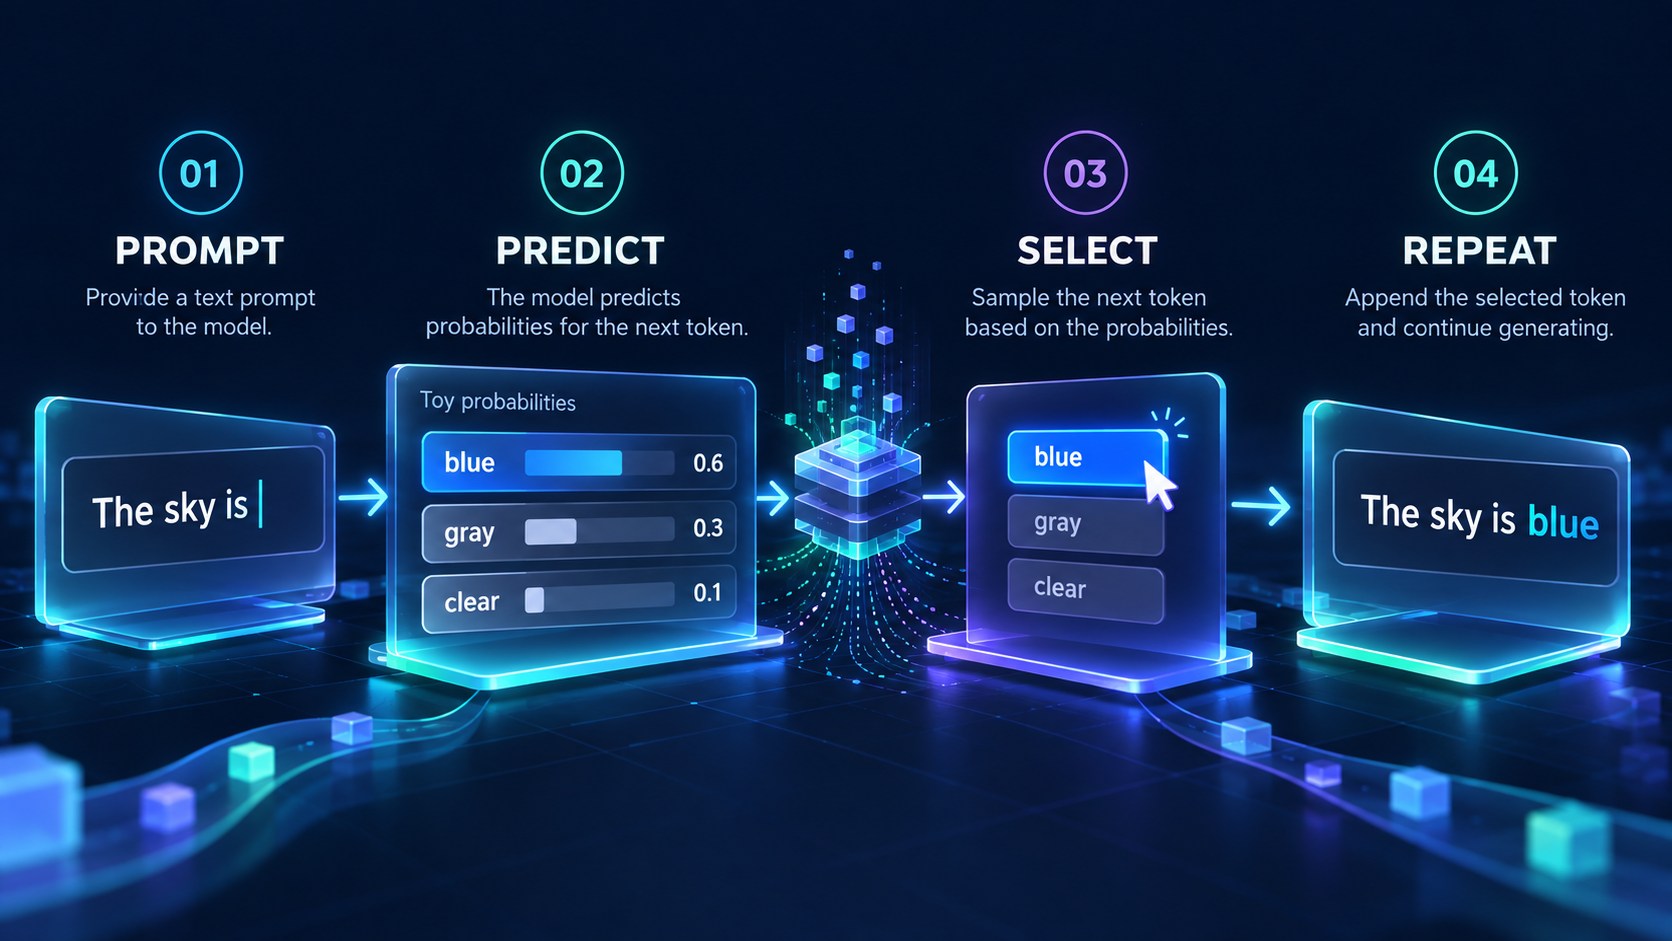
The core idea
A large language model learns statistical structure from large collections of text. A generative model estimates which token could follow the current context. Repeating this operation produces an answer, summary, translation, or program.
Parameters, context, and output
Parameters are learned numerical weights. Context is the information supplied for this particular response. Output is generated from both. A model can produce a plausible sentence that is factually wrong; fluent wording is not evidence of truth.
Training versus inference
Training adjusts weights to reduce prediction error. Inference normally keeps weights fixed and uses them to produce outputs. Pretraining is often followed by additional training; training is not necessarily a one-time event.
What makes the interface useful
Natural-language instructions let one model support many tasks. Capabilities still depend on training, context, tools, and evaluation. The model is not automatically connected to a database or the internet.
Worked example
A tiny probability table demonstrates next-word prediction. It is a hand-built teaching example, not a trained LLM. The first step chooses blue; the second chooses today.
Download lesson 01 Python example
transitions = {
    "The sky is": {"blue": 0.6, "gray": 0.3, "clear": 0.1},
    "The sky is blue": {"today": 0.8, ".": 0.2}
}
text = "The sky is"
for _ in range(2):
    choices = transitions[text]
    next_word = max(choices, key=choices.get)
    text += " " + next_word
print(text)
Expected output
The sky is blue todayEach iteration extends the context. Real models compute probabilities from learned weights over token IDs, rather than looking up a small dictionary of whole words.
Practice and self-check
Common mistake
Prediction is not verification. A model can predict the wording of an answer without having reliable evidence for its claims.
Student tasks
- Change the first distribution so gray becomes most likely. Add a transition for the new context.
- Explain whether loading a trained model and answering a question changes its weights.
- List two useful LLM tasks and a measurable success condition for each.
Checkpoint — open after attempting the tasks
Inference normally does not update weights. A good success condition is observable, such as extracting all three required fields correctly.