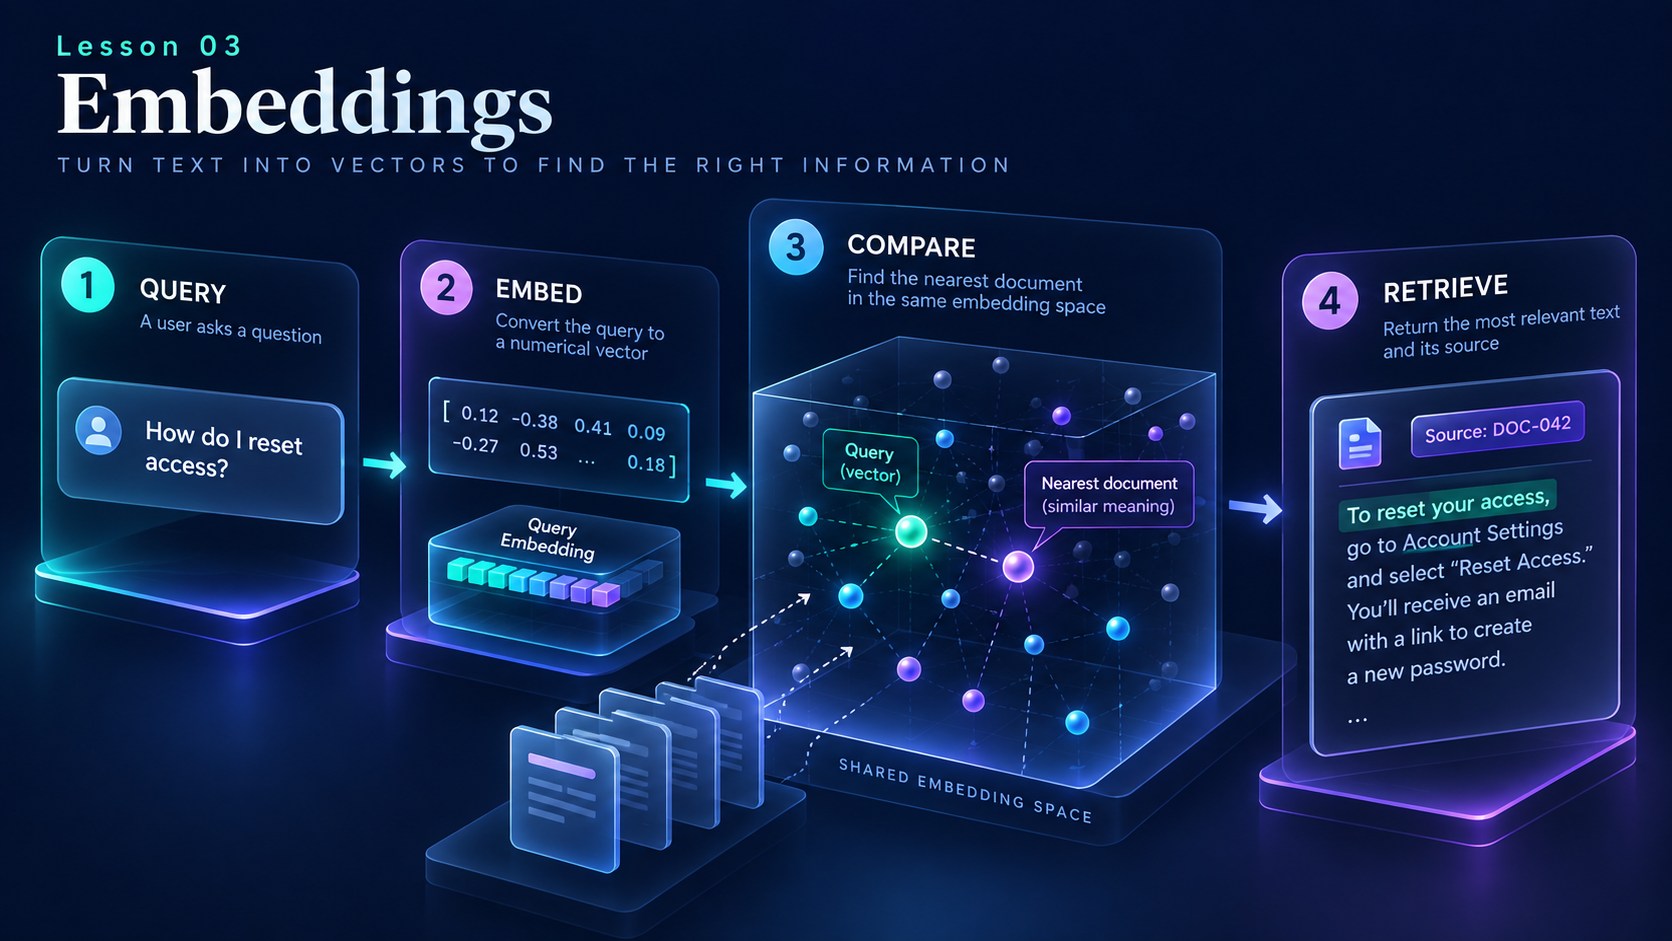
Dense representations
An embedding is a vector of numbers learned by a model. Unlike one-hot encoding, its dimensions can represent distributed features. Dimensions do not generally have simple human-readable labels.
Token versus sentence embeddings
A token embedding is often an input lookup vector. Transformer layers turn it into a context-dependent representation. A sentence or document embedding is produced by an embedding model and pooling or another trained mechanism; it is useful for retrieval.
Cosine similarity
Cosine similarity is dot(a,b) divided by the product of vector lengths. It measures direction rather than magnitude. Values near 1 indicate similar direction; scores are meaningful within a compatible embedding space, not across arbitrary models.
Retrieval applications
Store vectors with source IDs, text, and permissions. Embed a query with the same compatible model, rank candidate documents, and retrieve the relevant text. Similarity does not prove the retrieved text supports the answer.
Worked example
Compare invented two-dimensional vectors for cat, dog, and car. They illustrate the calculation; production embeddings are learned and usually have many more dimensions.
Download lesson 03 Python example
from math import sqrt

vectors = {"cat": [1.0, 0.2], "dog": [0.9, 0.3], "car": [0.1, 1.0]}

def cosine(a, b):
    dot = sum(x*y for x, y in zip(a, b))
    return dot / (sqrt(sum(x*x for x in a)) *
                  sqrt(sum(y*y for y in b)))

for word in ("dog", "car"):
    print(word, round(cosine(vectors["cat"], vectors[word]), 3))
Expected output
dog 0.992
car 0.293
The dog vector is closer in direction to cat than car is. This toy geometry represents an intended relationship; it was not discovered by training.
Practice and self-check
Common mistake
Never compare stored vectors from one embedding model with query vectors from an incompatible model.
Handle zero vectors before dividing.
Student tasks
- Add a bicycle vector close to car and compare their cosine similarity.
- Explain why document embeddings are useful for search even when wording differs.
- Describe the metadata you would keep so a retrieved paragraph can be cited.
Checkpoint — open after attempting the tasks
Keep a stable document ID, location/page or section, version, text, and relevant access-control metadata.