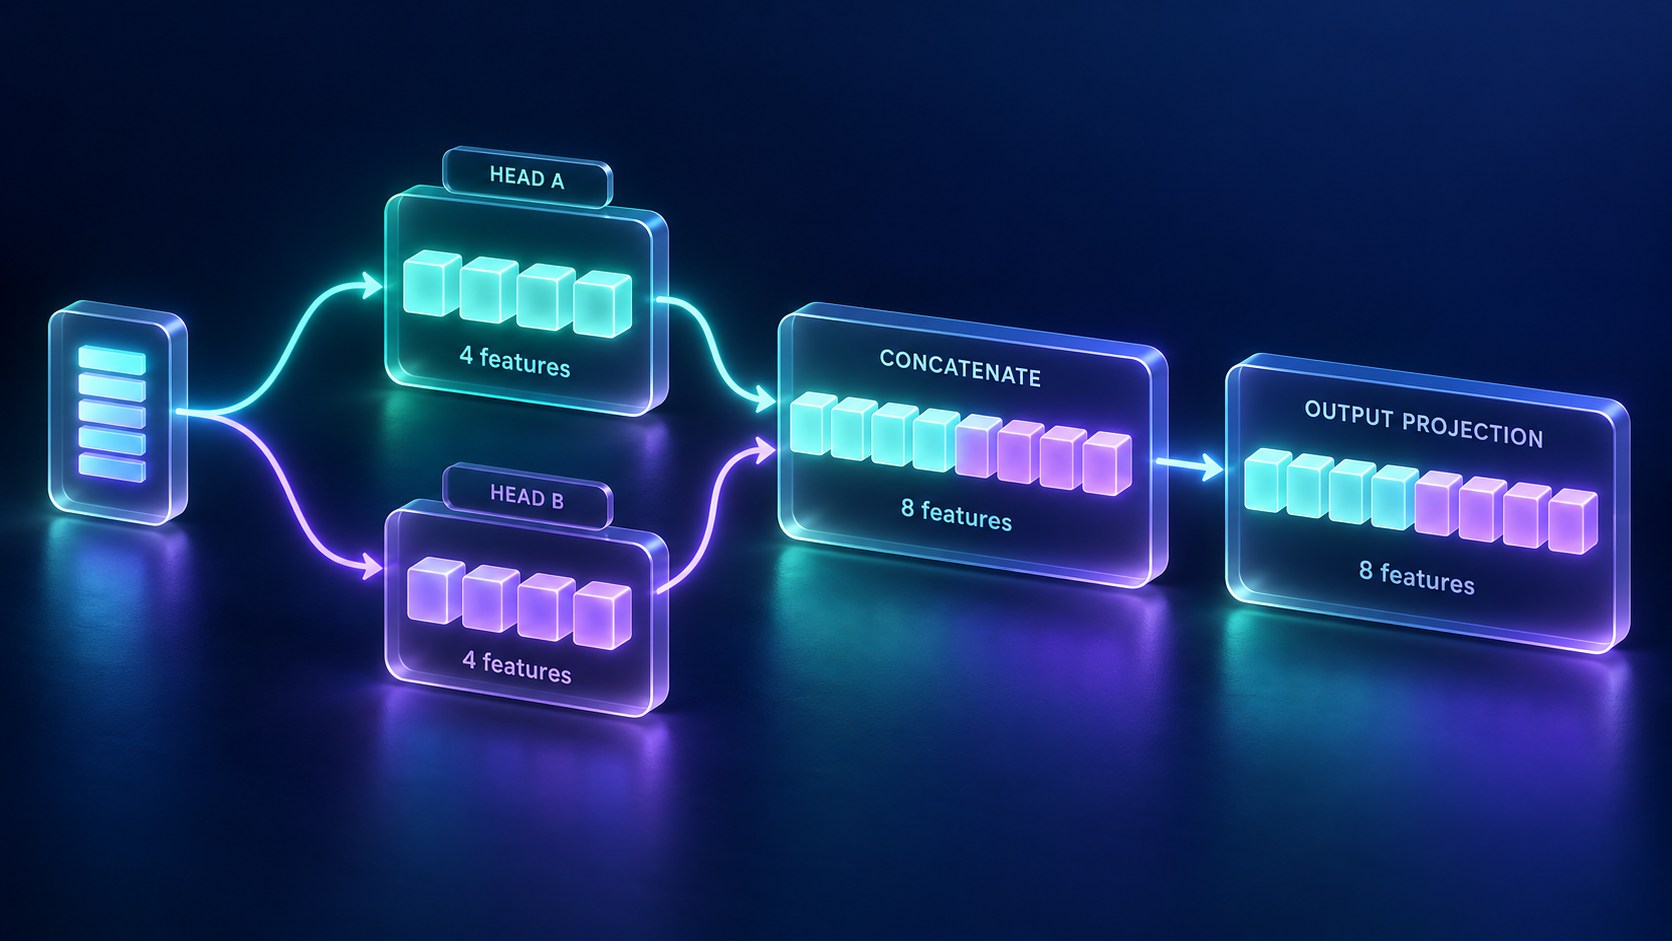
Several learned views
Multi-head attention uses different learned projections to compute multiple attention outputs. This lets the model represent different relationships at the same time. A head is not explicitly assigned to grammar or coreference unless an architecture or training setup imposes that.
Concatenate, then project
For h heads, concatenate their outputs along the feature dimension, then multiply by the output projection
W_O. In the common equal-width setup, d_head = d_model / h; each head attends across token positions.
Shape bookkeeping
For n tokens and d_model=8 with two heads, each head can produce an n by 4 output. Concatenation produces n by 8. The output projection maps this back to the model width.
Compute and variants
Multiple heads increase representational flexibility, not automatically speed. Grouped-query and multi-query variants share some key/value projections and can reduce cache requirements. The code below only demonstrates concatenation and output projection.
Worked example
Two invented head outputs are joined into a four-feature vector. A simple output matrix then mixes both heads into a new four-feature vector.
Download lesson 06 Python example
head_a, head_b = [1, 2], [3, 4]
joined = head_a + head_b
# Rows are input features; columns are output features.
W = [[1, 0, 1, 0], [0, 1, 0, 1],
     [1, 0, -1, 0], [0, 1, 0, -1]]
output = [sum(joined[i]*W[i][j] for i in range(4)) for j in range(4)]
print("Concatenated:", joined)
print("Projected:", output)
Expected output
Concatenated: [1, 2, 3, 4]
Projected: [4, 6, -2, -2]
The output is [4,6,-2,-2]. This shows that the final projection can combine information from different heads, rather than keeping the heads isolated.
Practice and self-check
Common mistake
Do not interpret a teaching label such as syntax head as a guaranteed learned role. Head specialization is an empirical observation, not a fixed contract.
Student tasks
- For model width 768 and 12 equal-width heads, calculate the width of one head.
- Replace W with a four-by-four identity matrix and predict the output.
- Explain why concatenation differs from averaging the two heads.
Checkpoint — open after attempting the tasks
One head has width 64. Identity projection preserves [1,2,3,4]. Averaging would collapse the two head vectors into only two features.